Antibiotic resistance
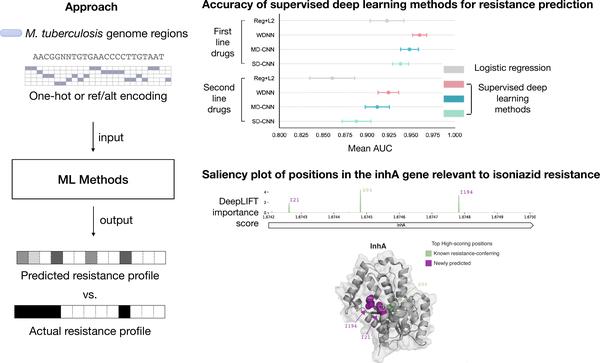
We seek to build the next generation of machine learning models to predict which strains of Mycobacterium tuberculosis are resistant to antibiotics. Our work has introduced convolutional neural networks that predict resistance (Green et al.) and MICs (Kulkarni et al.), and found new hypothesized mechanisms of resistance (Reimer et al.). We have also developed a method to predict which currently circulating variants may in fact cause resistance (Tasmin et al.). Now, our work involves experimenting with new architectures, datasets, and modalities of information to improve our models.
Interpretability of biological sequence models
Machine learning models of biological sequences can make accurate predictions, but how do we know whether those predictions are being made based on the correct underlying biological mechanisms? This is critical for using our models to discover new biology. Our work has used causal activation patching to understand the use of internal representations in protein language models (Nainani et al.). We have shown that for tuberculosis, large pre-trained models of sequences don’t reliably outperform small task-specific models (Tasmin et al.).Machine learning for small molecules
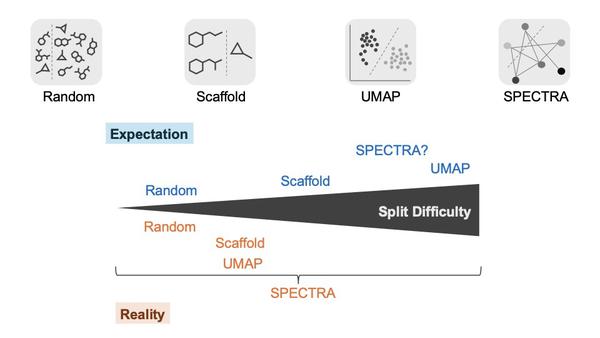
We want models that can reliably make predictions about the properties of a new molecule — will it permeate a membrane? Will it inhibit a particular protein? — both to guide drug discovery and to inform our understanding of biological processes. We aim to build models that will be accurate across the vast reaches of chemical space. Our work has shown that fusing different representations of chemical compounds improves prediction accuracy (Evbarunegbe et al.) and active learning trajectories (Evbarunegbe et al.). Our work has also shown that the way the field currently splits chemical space may not reliably measure generalizability, and suggests a better way (Reimer et al.). In collaboration with microbiologists, we produced a machine learning model of compound permeability through the mycomembrane (Lepori et al.), with the goal of informing future antibiotic development.